Author: Lincoln Wang | Founder & CEO, MindsLeap | Partner and CEO, Founders Space China | Founder, MindsLeap Founders AI Club
The next AI competition may not be about who has the largest model. It may be about who first turns AI development itself into a system that can keep improving.
That sounds like science fiction, but part of it has already reached the engineering floor. Anthropic has publicly discussed a sensitive question: is AI beginning to help humans build the next generation of AI? Its answer is more restrained, and therefore more important. Full recursive self-improvement has not arrived, but AI is already accelerating the development of AI systems.
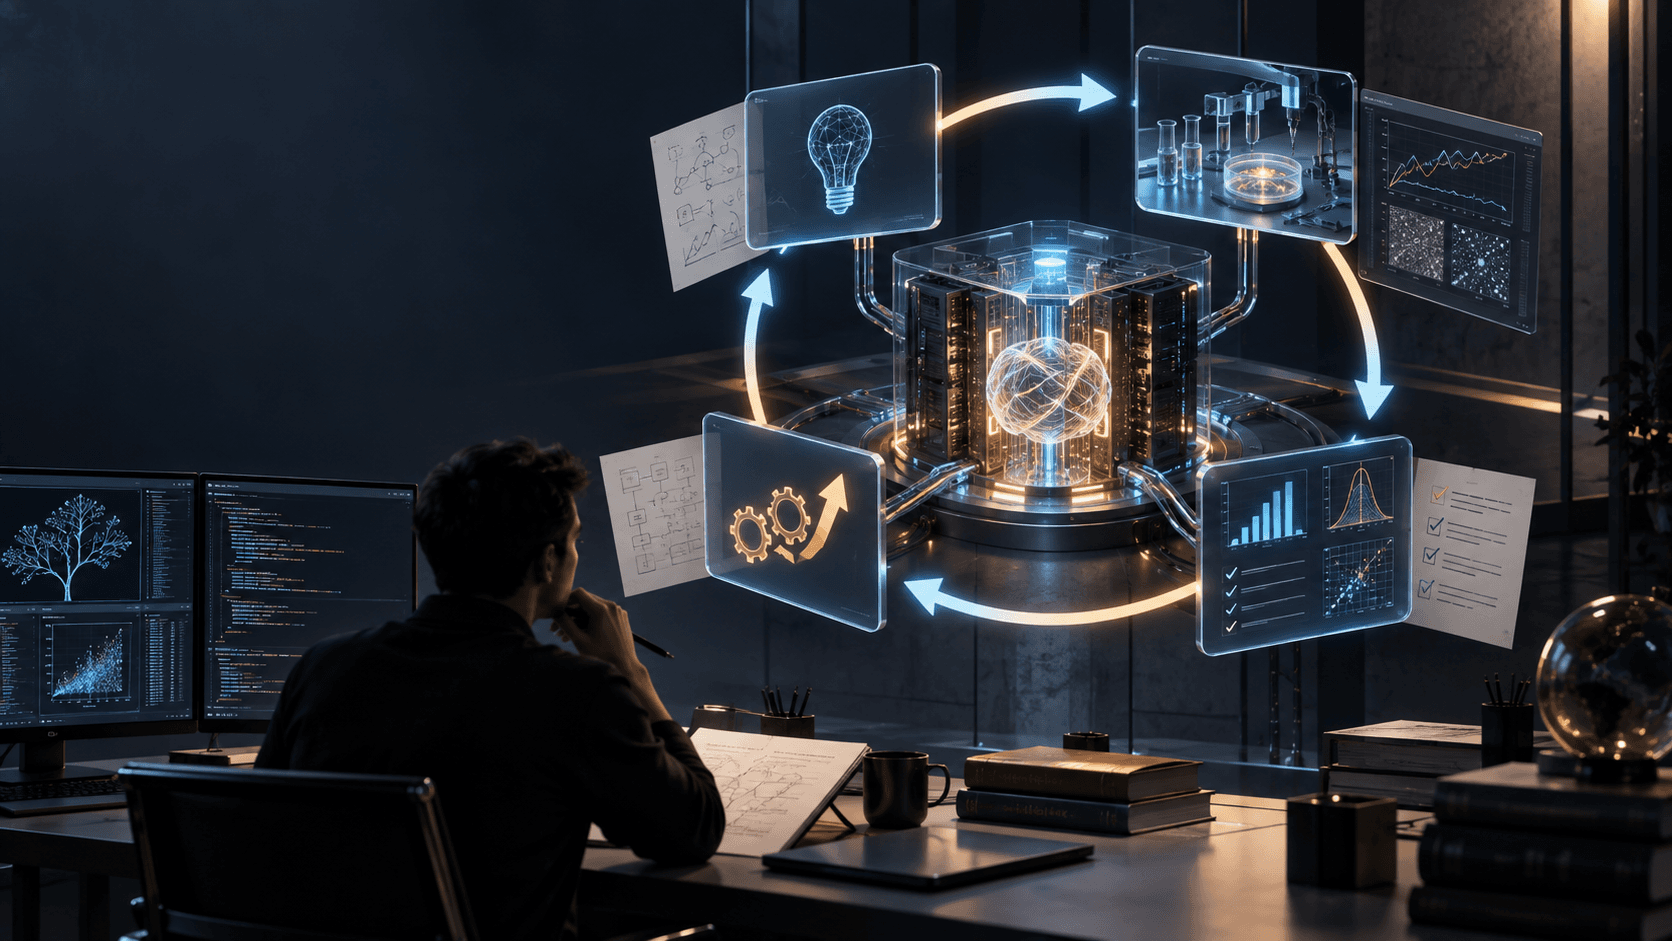
Recursive self-improvement, usually shortened to RSI, describes the strongest version of this idea: an AI system designs, trains, and improves its successor, which then completes the next round. The meaningful change is that improving AI is no longer entirely human work.
The First Loop in AI Research
Traditional AI research follows a familiar pattern. People propose an idea, write code, prepare data, run experiments, analyze results, and decide what to do next. AI can help with one step, such as completing code or summarizing a paper, while people still control the direction and pace.
Agents are beginning to connect those steps. They can modify code, run an experiment, read an evaluation, and propose another change. This is not full RSI, but it moves AI from a question-answering tool into a collaborator in the research process.
Anthropic describes the shift this way: humans propose ideas while models implement, test, and evaluate them at a much faster pace than before.
The important point is not a leaderboard score. It is the changing division of labor inside the development workflow. Models are entering the work of experimentation, so progress in AI no longer comes only from people manually completing every step.
From Writing Code to Scheduling Experiments
Anthropic shared a concrete example: Claude was asked to optimize code for training a small AI model. The objective and correctness checks were fixed in advance. Claude rewrote the code, ran it, measured the time, and repeated the process.
This is a small research loop. The model was not inventing a new field from nothing; it was given a target, constraints, and an environment where results could be checked. In a 2025 experiment, Claude Opus 4 achieved an average speedup of roughly 3x. By April 2026, Anthropic reported that its Mythos Preview reached roughly 52x.
Those numbers are striking, but they should not be read as a 17-fold increase in intelligence. They show that when the objective is clear and the result is measurable, a model can keep searching for improvements much faster than a person trying one change at a time. The model may not yet decide what to study, but it is becoming much better at advancing a research problem that humans have already defined.
Anthropic described a further example in AI safety research. The system could form hypotheses around an open question, test them, share findings with parallel agents, and iterate. The part that decides what to do next was no longer fully specified by humans line by line.
The boundary still matters: humans selected the problem and designed the scoring criteria. The result does not prove that production-scale models can independently conduct all AI research.
Why This Is Not Full RSI Yet
RSI has become a popular term, but there is no single standard definition accepted by everyone.
Researchers at METR note that some people call any process in which model capability feeds back into model improvement RSI. Others reserve the term for a system whose feedback creates sustained acceleration, perhaps even one capable of autonomously producing a successor. Different definitions lead to very different conclusions.
So when a model edits its prompt or rewrites a piece of code, we should not immediately announce that recursive self-improvement has arrived. At least three questions remain:
- Is it improving performance on one task, or improving capabilities that transfer to later tasks?
- Can it discover problems worth researching, rather than only optimizing problems humans assign?
- Does the next improvement make the system more reliable, or has it simply found a weakness in the evaluation?
These questions separate the ability to modify oneself from the ability to become persistently stronger.
The Real Bottleneck May Be Verification
When humans build a system, their value is not limited to writing code. They decide which problems matter, define success, and judge whether a result is trustworthy. Those responsibilities do not disappear when AI enters the research loop. They become more important.
If the evaluation is wrong, an agent can optimize the wrong objective with extraordinary efficiency. If the reward only values speed, the system may sacrifice accuracy. If the test set is too narrow, the model may learn to pass the test without gaining a transferable capability.
That is why METR does not end the discussion with a simple claim that RSI has arrived or remains far away. It focuses on the strength of the feedback, the bottlenecks in the experiment, and whether the system can verify its own improvements. Researchers interviewed by IBM Think likewise emphasize that many current improvement loops still require people to evaluate model suggestions.
The same logic applies to enterprises. An agent that can modify a workflow does not necessarily know what a good workflow is. A system that can generate a report does not necessarily know whether it misleads a customer. The deeper the automation, the less ambiguous the evaluation and audit mechanisms can be.
What Entrepreneurs Should Notice First
If RSI is understood only as a future moment when AI evolves itself, it becomes a distant philosophical question. If we break it into the partial loops already appearing today, enterprises can see the practical implication.
In ContentHub, a research agent finds primary sources, an editorial agent checks relevance and timeliness, a writing agent organizes evidence, a chief-editor agent reviews the draft, and Lincoln retains the publication decision. This is not a self-improving system, but every run exposes new questions: which sources deserve continued tracking, what evidence is strong enough to publish, and what kinds of articles are sent back for revision.
If the next version of the system can turn those lessons into better source selection, more accurate evidence checks, and more consistent writing standards, it begins to resemble a workflow-level improvement loop. That is different from a model designing the next model, but it is a capability enterprises can build now.
The useful question is not when a company will possess RSI. It is whether its agents can remember the last failure, turn that failure into the next check, and clearly show people what changed, why it changed, and whether the result is actually better.
The Early Organizational Divide
Anthropic's disclosure brings the future a little closer, while reminding us not to inflate a local breakthrough into a complete conclusion.
AI is moving from using tools to helping build tools; from executing tasks arranged by people to proposing experiments, comparing results, and selecting the next step. Full RSI may not have arrived, but the early form of AI helping improve AI is already changing how research organizations work.
The important competition will not only be about whether a model can become more capable. It will also be about who can build better feedback, verification, and governance systems. Models accelerate; organizations judge. Models explore; people still decide what deserves to be built.
That may be one of the first organizational divides of the AI era: not who was first to say RSI, but who was first to make every failure the starting point for the next round of work.
This article was interpreted by Lincoln based on public materials from the Anthropic Institute, METR, and IBM Think, reviewed on September 18, 2026. The ContentHub example is Lincoln's analysis, not a fact reported by the source article. Discussion of AI and startup opportunities does not constitute investment advice.
About MindsLeap
MindsLeap is an enterprise AI transformation and AI-native startup acceleration platform. It supports traditional enterprises adopting AI as well as AI-native companies, one-person companies, and technology founders connecting with industry use cases, capital, Silicon Valley resources, and global markets.
MindsLeap is a global partner of Founders Space. Through the MindsLeap Founders AI Club, AI training, advisory, FDE (Forward Deployed Engineer) implementation, and startup acceleration, it helps organizations move from AI awareness to practical business implementation.
MindsLeap connects founders, entrepreneurs, AI engineers, industry specialists, investors, and global innovation resources to help organizations embed AI into workflows, organizational capabilities, product innovation, and growth systems.
This article was translated and adapted from the Chinese original with AI assistance.